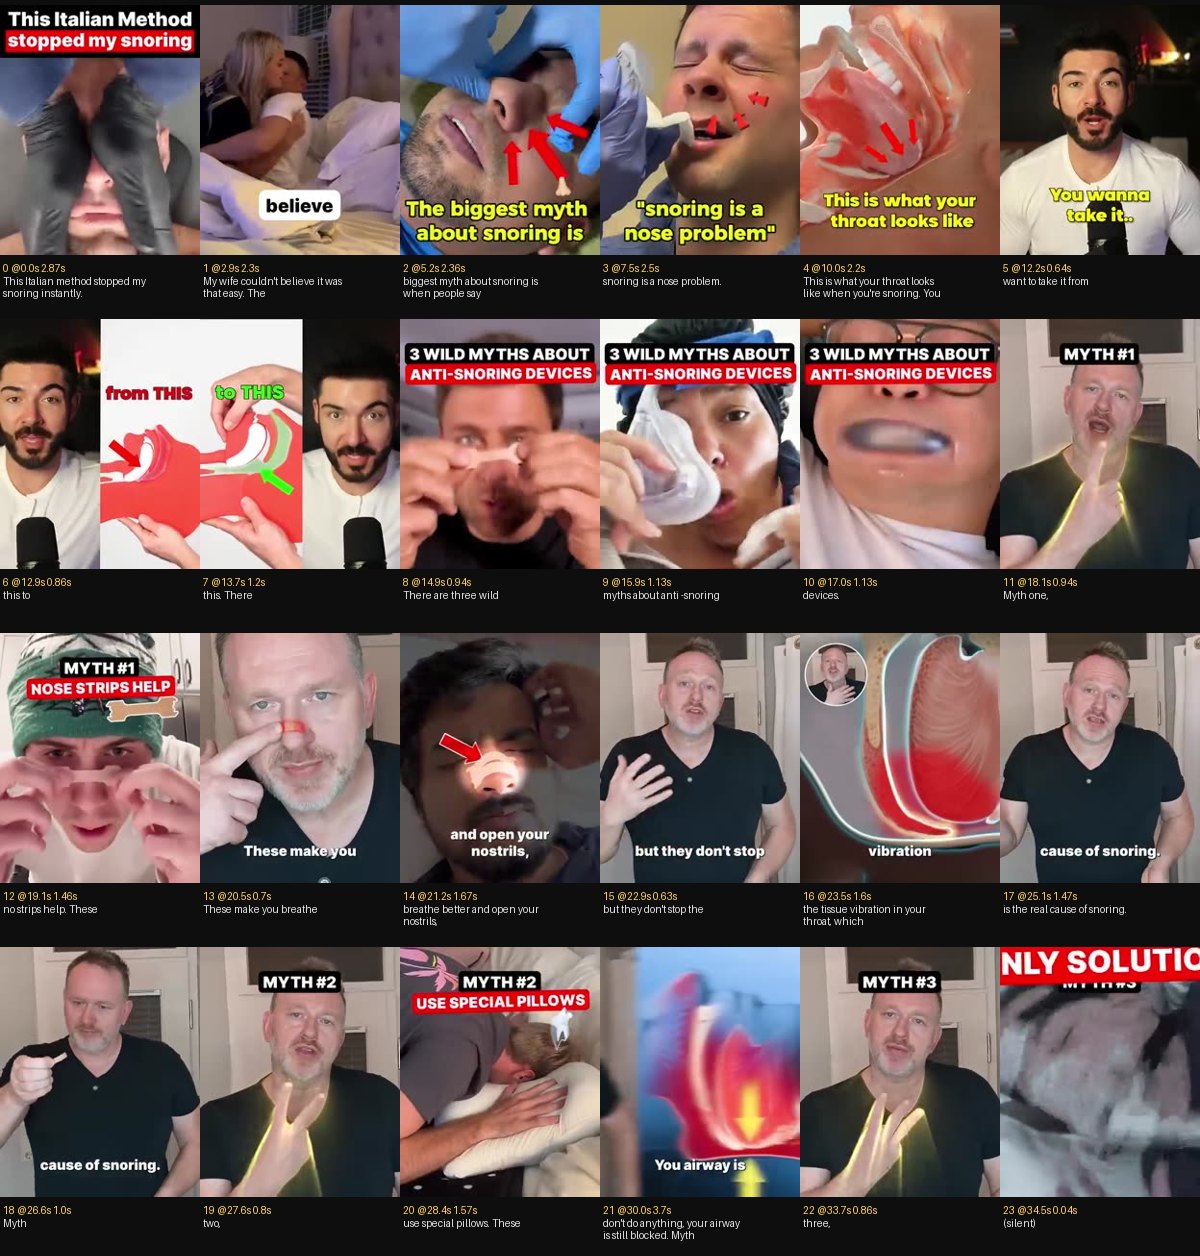
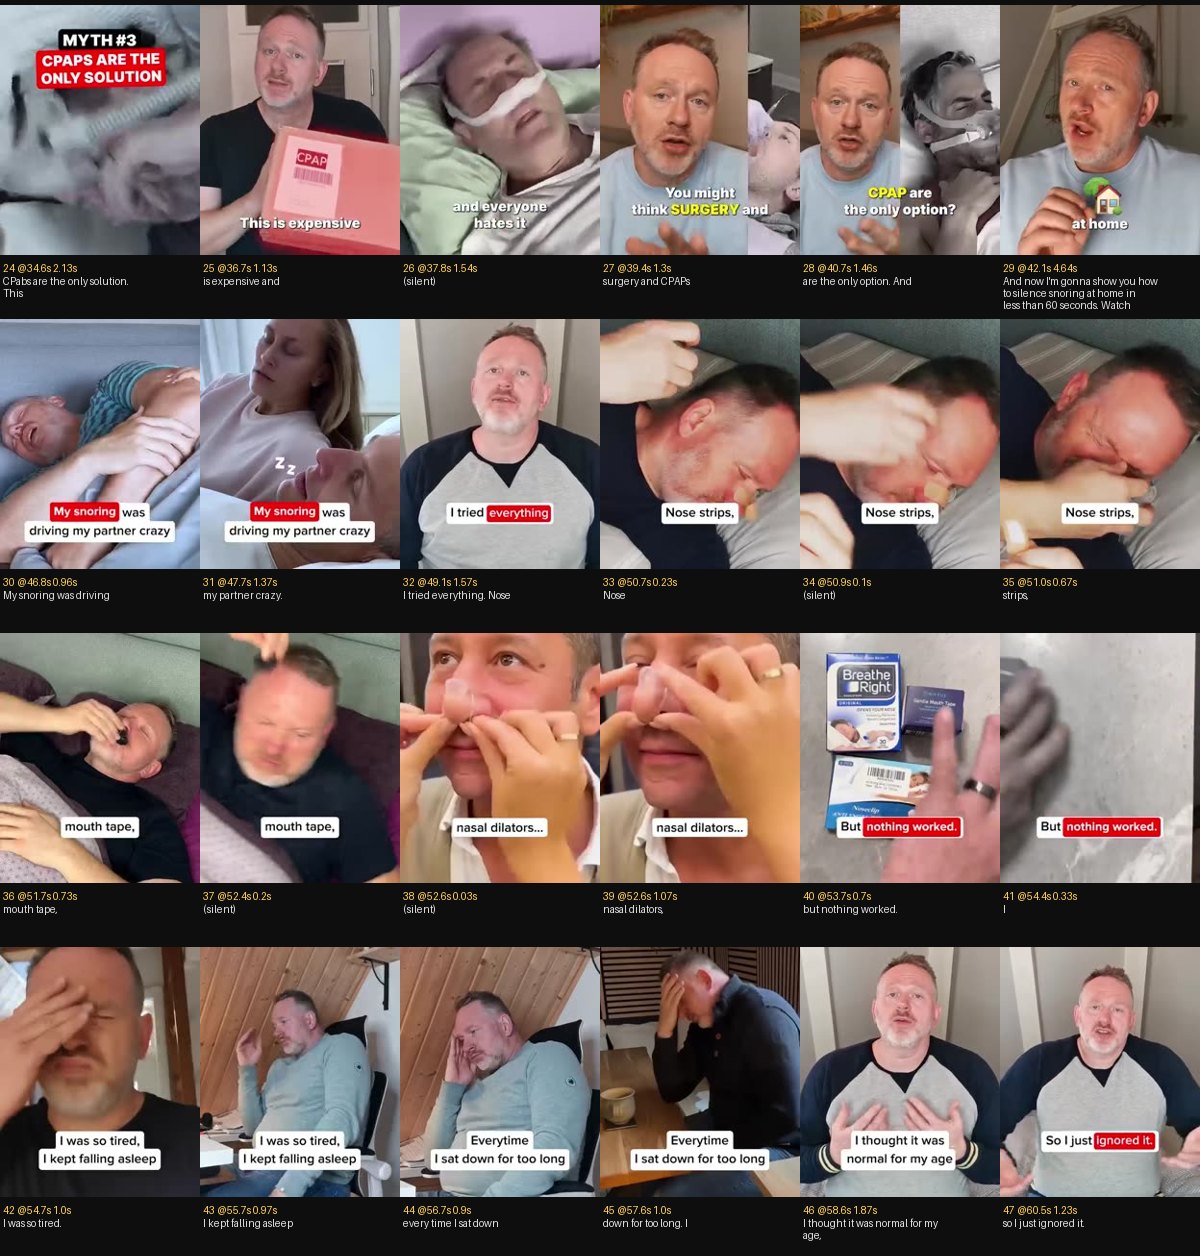
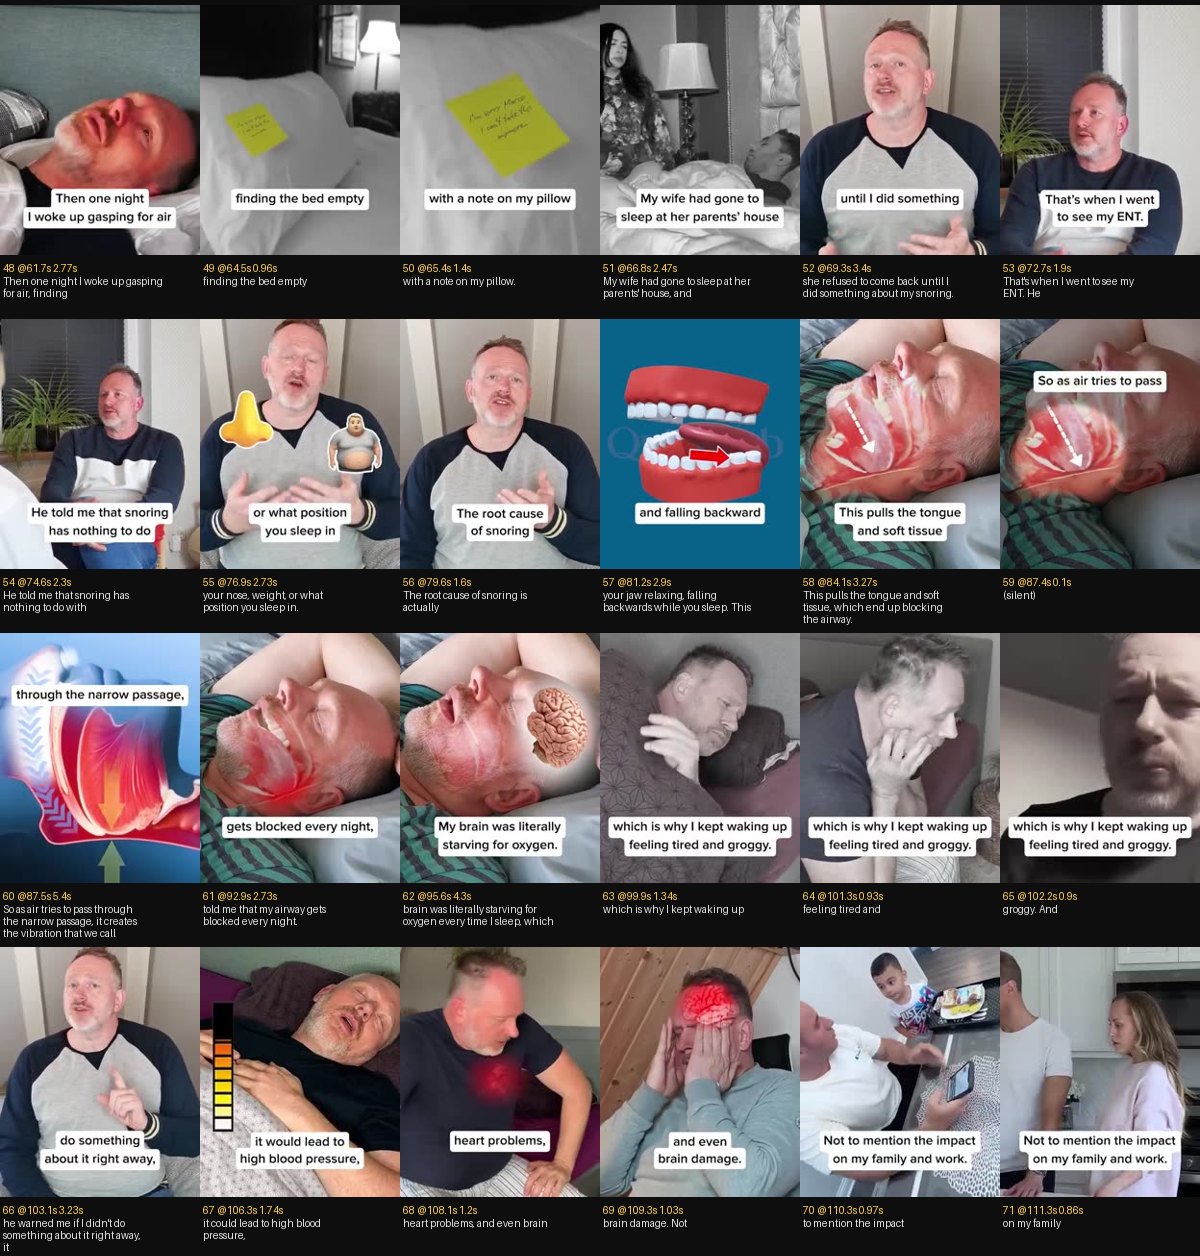
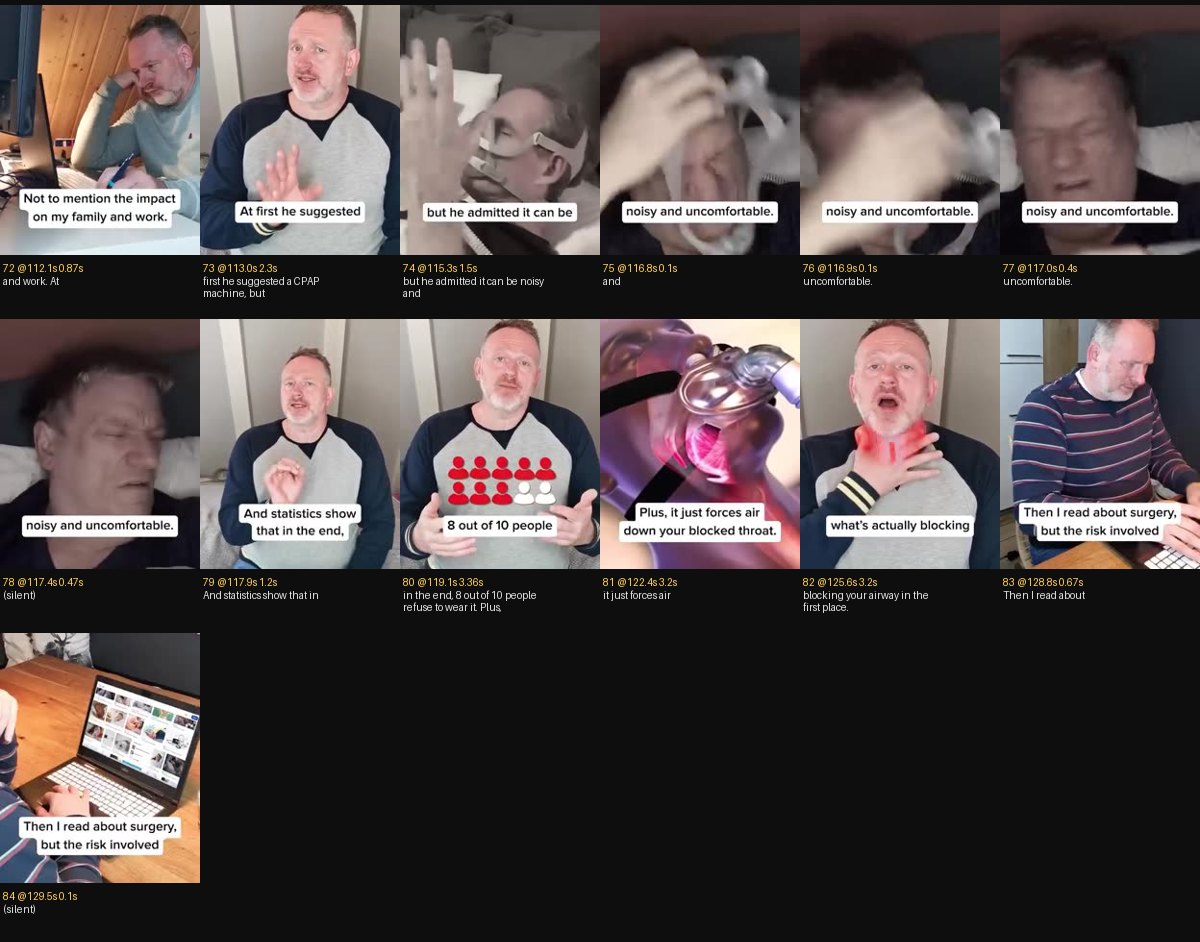
QuietLab · what is actually on screen, shot by shot
The question: does every QuietLab clip illustrate the line being spoken, is there such a thing as a filler clip, and what do they put on screen when the copy goes generic.
quietlab brand tag in our digests.
Four of them are not QuietLab — they are a survival and heating advertiser (“If every water bottle was
gone tomorrow”, “Don’t make this mistake during a winter storm”). Of the four that are, seven of
eight archived files are capped at exactly 5,000,001 bytes (the AdSpy preview cap), so each decodes to 30–51% of its
runtime while reporting the full duration. This study is therefore one ad read in full detail — the Q5 donor,
its first 129.6s, all 85 shots — with a second ad measured for pacing. The closes of every long ad are unexamined.The answer
In 85 shots there is no filler. Every shot is tied to the line over it. There is no such thing as a filler clip at QuietLab, and the reason is structural rather than a matter of better picture-hunting.
When the line goes generic, they cut to the presenter’s face and put the sentence on screen as text. The presenter is the universal fallback, and he carries 28% of the ad. These are the lines he covers:
0.0s“This Italian method stopped my snoring instantly.”12.9s“this to”14.9s“There are three wild”18.1s“Myth one,”19.1s“no strips help. These”22.9s“but they don't stop the”25.1s“is the real cause of snoring.”26.6s“Myth”27.6s“two,”28.4s“use special pillows. These”
Every shot also carries the spoken line burned in as large styled text, so the copy is read as well as heard. The picture never has to carry an abstract idea alone.
Every shot, classified by eye
| what is on screen | shots | share |
|---|---|---|
| literal-prop | 27 | 32% |
| presenter | 24 | 28% |
| symptom-reenact | 20 | 24% |
| anatomy-render | 10 | 12% |
| stat-graphic | 2 | 2% |
| title-card | 2 | 2% |
| filler (unrelated to its line) | 0 | 0% |
Why ours cannot do this
S1, S3 and Q1 are B-roll with a voiceover and no presenter. QuietLab’s ad is a talking head with cutaways: the face is the home base and the ad leaves it to illustrate each concrete noun, then returns. When our copy goes abstract we have nowhere to return to, so the edit reaches for a loosely related clip. That is the mechanism behind “it can talk about one thing and show another”.
The second difference is sentence length. QuietLab writes 3.7s sentences; S1 writes 5.5s. Per sentence we spend 2.05 shots against their 2.49, so we are not far off — but a long sentence makes the picture look like it wandered off, because it has to cover half a thought.
Measured
| QuietLab Q5 donor | ours, S1 | |
|---|---|---|
| seconds per shot | 1.52 | 2.70 |
| seconds per sentence | 3.7 | 5.5 |
| shots per sentence | 2.49 | 2.05 |
| presenter on screen | 28% of shots | none |
| line burned on screen | every shot | running captions only |
All 85 shots, with the words spoken over each